NERD OUT
Here's how it works
The Stack
Here's what's under the hood, for those who want to know.
The phone apps are the real thing - native on both iPhone and Android, built separately for each with React Native and Expo, and when the phone's own frameworks are needed we write Swift and Kotlin. The fitness app, for example, does its pose detection right on the phone using Google's MediaPipe pose model - the same model on both phones. The web app is Next.js and its own codebase; nobody squeezed a phone app into a browser. All three share one TypeScript core with strict schemas, so a rule written once holds everywhere. By default, each phone app does everything that the web version does, but we can and do segment by use case. For instance, the fitness app is phone-first, with the web version offering different, complementary capabilities.
Data and server logic live in Supabase - Postgres plus functions on Deno - and every change to a job's state has to go through a small set of guarded doors in the database. No sneaking around the back. The longer-running work - each Designosaur's own worker and the model gateway - runs on Google Cloud Run, where a job can run past a Supabase function's 150-second limit. Web releases go out on Vercel through previews, staging and production, GitHub Actions runs the tests, and pnpm holds the packages together.
A theme engine and a thirty-six-theme library (and growing weekly) give every app three switchable themes; you're looking at that on this page. Email gets pulled from the accounts by a Supabase function and sorted with routed models; texts come off the Mac. And a Hetzner box, run with Coolify, hosts the browser stack we use for harvesting and measuring. The database already runs on AWS, and the rest is built from portable parts - Postgres, Deno functions, Next.js and containers - so the entire system could be migrated to AWS if needed.
Where it all runs:
| Where | What Runs There |
|---|---|
| Supabase, on AWS | The database of record, 62 server functions, 35 database clocks, file storage, search by meaning, and sign-in for the apps we ship |
| Google Cloud | 13 services on Cloud Run - the Designosaurs' 11 workers, the model gateway and a mockup renderer - plus Cloud Build, Secret Manager, a small database for the gateway, and Cloud Scheduler |
| Vercel | Every web app, with its previews and its staging copy |
| GitHub | The code, every change as a pull request, and 45 automated workflows: tests, supply-chain tests and releases |
| A Hetzner box, run with Coolify | The shared browser service (Playwright, browser-use and Crawl4AI) behind HTTPS |
| The Mac | The coding fleet, the iPhone and Android simulators, and nine scheduled jobs: the texts reader, Podium's Ask Claude runner, the pull-request gate runner, a health probe every fifteen minutes, and an encrypted nightly backup with a restore drill |
| 1Password | Every key, in one vault, copied out to the places above that need it |
It also talks to Google Workspace (mail in, approved replies out, Calendar and Tasks), HubSpot (read only), Resend for alerts, and Serper for search.
Tomorrow: Store builds, payments and phone test flows - each one started, none switched on yet.
How We Choose Which AI Model Does Which Job
Almost every request we send to an AI model goes out through one door - a LiteLLM gateway on Google Cloud Run - so a request reaches a model only by a route we chose. The door is set up from one list we keep: the registry. Each model on it has an entry that says what it can do, what it costs, who makes it and where that company is based, what license its weights carry, how long the maker keeps what we send, and whether the maker trains on it. A model that isn't on the list can't be called through the door.
One kind of request doesn't use the door yet: turning text into numbers so it can be searched by meaning. The email sorter does that every five minutes by calling the maker directly. Moving those calls behind the door is on the list.
Models are grouped by the job, not by the brand. Each group has a first choice and backups, so if one maker has a bad day the request moves to the next:
| Group | What It's For | Who Uses It | First Choice |
|---|---|---|---|
| Deep reasoning | Planning, hard calls, the builder's last attempt | Ada, Trully's design review, the research agents | Claude Fable 5.1 |
| Standard work | Most writing and code | Ada, Cleo, Dromeo, Val, Tycho, Penny | Claude Sonnet 5.5 |
| Review | Quality and security review | Trully, Sun-sin, Wolfgang | Gemini 3.8 Flash |
| Long-form writing | Brainstorming, synthesis, research with search | Dromeo, Podium's briefing, the research agents | Claude Fable 5.1 |
| Quick and bulk sorting | Sorting email, reading intent, summaries | The email sorter, Wolfgang's front door | Gemini 3.5 Flash Lite |
| Search by meaning | Turning text into numbers for search | Pattern search | Gemini Embedding 2 |
Each role also has a set effort level - how long a model may think and how much it may write. It's extra-high for Cleo, Ada, Trully's design review and Dromeo's long passes; high for Val, Trully, Dromeo's core work and Tycho's extraction; medium for Sun-sin, Tycho and Wolfgang; and low for Penny and the email sorter. A test runs on every change to the list, so a role can't quietly move to a model or an effort the list doesn't allow.
We track how every model performs, wherever it's made, so we know our costs stay competitive with the rest of the world. We use only models made in democratic countries, and a test fails the build if a route ever points anywhere else.
Keeping it current. A probe runs every morning. It reads the makers' model lists and what's trending, and files each new model as work for review. A research pass then reads the model's own pages and the independent scoreboards and fills in its entry - what it can do, its prices, the company's country, the weights' license, how long the maker keeps data and whether it trains on it - with a date and a link for each. A score we couldn't read from an independent source goes in as unknown, not guessed.
Getting on the list isn't getting a route. Before a model carries real work:
- It answers live through the door, using the same code our roles use, so we know its replies come back in the shape our code expects.
- It's tested on the job it would do, with tests that don't ask another model's opinion. The builder's test is 63 matched tries against a frozen baseline, scored by fixed tests; a newcomer has to come within three points of the baseline or beat it. A review model has to find the real faults in a set of known cases. A sorting model is judged side by side against the one it would replace.
- Its price and terms are set against the one it would replace, and its country and data terms compared with our rules.
- The change goes out first on a copy of the gateway that carries no traffic. It gets probed there, and only then takes over - with the old copy kept to roll back to.
- After that, every group is probed every thirty minutes. Each model change sets off a re-read of the scaffolding around it, so we drop workarounds the new model no longer needs.
How a change gets made. A newer model from the same maker - no more expensive, with an independent score at least as good and the same country and data terms - may take a backup slot, or first place on the quick jobs, on its own, with me told. Anything bigger, like a different maker or a new first choice for reasoning, is laid out as a case and waits for my yes. Anything without an independent score, or outside our rules, never switches on its own. For now all of these are made by hand, each with a written record.
Two changes from September 2026. Claude Sonnet 5.5 came out on September 28th, 2026. The next day it was on the list and in a backup slot for reasoning; on the 30th it beat the builder's frozen baseline by six points, I said yes, and it became the first choice for standard work - eight of eight probes answered. GPT-6 Astra became the second reader on reasoning in early September. On September 29th, three of six probes failed - our gateway's version was too old to talk to it properly - so it came off that evening. We upgraded the gateway, tested it on a copy with no traffic, and the next day it went back on, six for six.
For the mail sorter below, we require no retention or training on our mail, test on masked email, and leave every contact to me. Jev, a new decision model from TypeSafe AI, sorts at a small fraction of what our current sorter costs and answers in well under a second. In September we held off, because by default it kept what we send. It can now run with nothing kept and no training on our mail, through a gateway we already pay for. Its trial is on masked email, judged against my own labels, and if it beats our current sorter, it takes over sorting.
Today: 83 entries on the list - 82 models from 15 makers (one is listed twice, because we can reach it two ways); 11 on routes, 2 on trial, 62 tracked and 7 retired; the door is rebuilt only from the list. Jev is under evaluation, and three image and video tools made this site's pictures.
On a Route (11)
| Model | Maker | Made in | Weights | How it fits | Price band | Independent score |
|---|---|---|---|---|---|---|
| Gemini Embedding 2 | United States | closed | Search by meaning (first choice) | very low | none on file | |
| Claude Opus 5 | Anthropic | United States | closed | Standard work (third); review (second); long-form writing (third) | premium | independent |
| Claude Sonnet 5.5 | Anthropic | United States | closed | Deep reasoning (third); standard work (first choice) | high | independent |
| Claude Fable 5.1 | Anthropic | United States | closed | Deep reasoning (first choice); standard work (second); long-form writing (first choice) | premium | independent |
| GPT-5.4 | OpenAI | United States | closed | Standard work (sixth) | high | independent |
| GPT-5.4 mini | OpenAI | United States | closed | Quick sorting (second); bulk sorting (second) | mid | none on file |
| GPT-6 Astra | OpenAI | United States | closed | Deep reasoning (second) | premium | independent |
| Gemini 3.8 Flash | United States | closed | Standard work (fifth); review (first choice); long-form writing (second) | mid | independent | |
| Gemini 3.5 Flash Lite | United States | closed | Quick sorting (first choice); bulk sorting (first choice) | low | none on file | |
| Grok 4.6 | xAI | United States | closed | Standard work (fourth); long-form writing (fourth) | mid | independent |
| GPT-OSS 20B | OpenAI (served by Groq) | United States | open (Apache-2.0) | Quick sorting (third); bulk sorting (third) | very low | independent |
On Trial (2)
| Model | Maker | Made in | Weights | How it fits | Price band | Independent score |
|---|---|---|---|---|---|---|
| GPT-5.6 Terra | OpenAI | United States | closed | Trial by exact name only, no fallback: measures the builder's repair step | high | independent |
| Gemini 4 Argon | United States | closed | Trial by exact name only, no fallback: measures the builder's repair step | high | maker's own only |
Being Evaluated (1)
| Model | Maker | Made in | Weights | How it fits | Price band | Independent score |
|---|---|---|---|---|---|---|
| Jev (jev-1.13) | TypeSafe AI | United States | closed | A decision model for sorting email: it picks among our nineteen categories and says how sure it is, in about a tenth to half a second. Next: a trial on masked email against our current sorter; if it wins on my labels, it takes over sorting, with nothing kept and no training on our mail. | very low | independent studies; none on our mail yet |
Pictures and Videos on This Site (3)
| Model | Maker | Made in | Weights | What we made with it |
|---|---|---|---|---|
| Nano Banana (Gemini's image model) | United States | closed | The Designosaurs' portraits, their poses and the family portrait, made in Google's Antigravity and the Gemini app, January to June 2026 | |
| Veo (Google's video model) | United States | closed | The eight Designosaur intro videos, voices included | |
| Canva AI | Canva | Australia | closed | Wolfgang's Lycorhinus painting, September 26th, 2026 |
The Rest of the List (69)
| Model | Maker | Made in | Weights | How it fits | Price band | Independent score |
|---|---|---|---|---|---|---|
| Jamba Large 1.7 | AI21 | Israel | open (Jamba-Open-Model-License) | Pulled from routes July 15th, when the maker refused our calls | mid | independent |
| Jamba Mini 2 | AI21 | Israel | open (Jamba-Open-Model-License) | Pulled from routes July 15th, when the maker refused our calls | low | independent |
| Qwen 3.6 Plus | Alibaba (Qwen) | China | open (Apache-2.0) | Tracked only: models from Chinese labs are never routed | mid | none on file |
| Claude Haiku 4.5 | Anthropic | United States | closed | A research helper, August to September; no independent score on file | mid | none on file |
| Claude Mythos 5 | Anthropic | United States | closed | Invite only | premium | none on file |
| Claude Mythos 5.1 | Anthropic | United States | closed | Invite only | premium | none on file |
| Claude Opus 4.7 | Anthropic | United States | closed | On routes April to September; the Chief Architect's model, April to June; still the frozen baseline the builder test measures newcomers against | premium | maker's own only |
| Claude Opus 4.8 | Anthropic | United States | closed | The Chief Architect's model, May to September | premium | maker's own only |
| Claude Opus 5.5 | Anthropic | United States | closed | Listed September 29th; no route until an independent score is published; the Chief Architect's model since late September | high | none on file |
| Claude Sonnet 4.6 | Anthropic | United States | closed | Kept for evaluation only; a research helper, April to May | high | maker's own only |
| Claude Sonnet 5 | Anthropic | United States | closed | A research helper in September; superseded by Sonnet 5.5 | high | independent |
| DeepSeek Flash | DeepSeek | China | not recorded | Tracked only: models from Chinese labs are never routed; license unknown | low | none on file |
| DeepSeek V4 Flash | DeepSeek | China | open (MIT) | Listed in a quick group from April 24th to May 7th, before the country rule; no calls on record | very low | none on file |
| DeepSeek V4 Pro | DeepSeek | China | open (MIT) | Tracked only: models from Chinese labs are never routed | very low | none on file |
| Gemini Deep Research Max Preview (April 2026) | United States | closed | Tracked | mid | none on file | |
| Gemini Deep Research Preview (April 2026) | United States | closed | Tracked | mid | none on file | |
| Gemini 2.5 Flash | United States | closed | Off routes since July 31st; the maker shuts it down October 16th | low | none on file | |
| Gemini 3.1 Flash Image Preview | United States | closed | Images; not a candidate for our roles yet | not captured | none on file | |
| Gemini 3.1 Flash Lite Preview | United States | closed | Preview; tracked | not captured | none on file | |
| Gemini 3.1 Flash Live Preview | United States | closed | Live audio; not a candidate for our roles yet | not captured | none on file | |
| Gemini 3.1 Flash TTS Preview | United States | closed | Speech; not a candidate for our roles yet | not captured | none on file | |
| Gemini 3.1 Pro Preview | United States | closed | First choice for review until September 9th; our quality architect's model in Antigravity, March to September | high | maker's own only | |
| Gemini 3.5 Flash | United States | closed | Passed the review test in May (found 6 of 7 known faults); used in Antigravity in May; superseded by 3.8 Flash | mid | maker's own only | |
| Gemini 3.6 Flash | United States | closed | Used in Antigravity, July to August | mid | independent | |
| Gemini 3.7 Flash | United States | closed | Tried in Antigravity in August | mid | independent | |
| Gemini Omni 1.1 Flash | United States | closed | Makes video; not a candidate for our roles | high | none on file | |
| Gemini 2.5 Flash | Google (Vertex) | United States | closed | Off routes since July 31st; the maker shuts it down October 16th | low | none on file |
| MiniMax M2.7 | MiniMax | China | open (factory-inferred-permissive) | Tracked only: models from Chinese labs are never routed | low | none on file |
| Codestral 2508 | Mistral | France | open (Mistral-Open-Weight) | Carried standard work May to August 2026; off the routes since the September refresh, no independent score | low | none on file |
| Leanstral 1.5 | Mistral | France | open (Apache-2.0) | Provisional entry | free (lab release) | none on file |
| Mistral Large 2512 | Mistral | France | closed | Carried standard work May to August 2026; off the routes since the September refresh, no independent score | low | none on file |
| Mistral Medium 3.5 | Mistral | France | open (Modified-MIT) | Provisional entry | mid | none on file |
| Mistral OCR 4 | Mistral | France | closed | Reads documents; superseded by OCR 4.1 | priced per page | none on file |
| Mistral OCR 4.1 | Mistral | France | closed | Reads documents; provisional entry | priced per page | none on file |
| Kimi K2.6 | Moonshot | China | open (Modified-MIT) | Tracked only: models from Chinese labs are never routed | not captured | none on file |
| Llama 3.3 Nemotron Super 49B v1.5 | NVIDIA | United States | open (NVIDIA-Open-Model-License) | Taken off September 13th, when the maker retired it | low | independent |
| GPT-5 Codex | OpenAI | United States | closed | Tracked | mid | none on file |
| GPT-5.1 Codex | OpenAI | United States | closed | Tracked | mid | none on file |
| GPT-5.1 Codex max | OpenAI | United States | closed | Tracked | mid | none on file |
| GPT-5.1 Codex mini | OpenAI | United States | closed | Taken off quick sorting September 13th, when the maker stopped answering for it | low | none on file |
| GPT-5.2 Codex | OpenAI | United States | closed | Coding in Codex and Cursor, until February 2026 | high | none on file |
| GPT-5.3 Codex | OpenAI | United States | closed | Coding in Codex, February to June | high | independent |
| GPT-5.4 nano | OpenAI | United States | closed | Tracked | low | none on file |
| GPT-5.4 Pro | OpenAI | United States | closed | Tracked | premium | none on file |
| GPT-5.5 | OpenAI | United States | closed | Deep reasoning from April to early September; our main coding model in Codex, April to July | premium | independent |
| GPT-5.5 Pro | OpenAI | United States | closed | Tracked | premium | none on file |
| GPT-5.6 | OpenAI | United States | closed | Another name for GPT-5.6 Sol | high | independent |
| GPT-5.6 Luna | OpenAI | United States | closed | Tracked | low | independent |
| GPT-5.6 Sol | OpenAI | United States | closed | Our main coding model in Codex, July to September | high | independent |
| OpenAI o3 | OpenAI | United States | closed | Tracked | premium | none on file |
| OpenAI o3-mini | OpenAI | United States | closed | Tracked | mid | none on file |
| OpenAI o4-mini | OpenAI | United States | closed | Tracked | mid | none on file |
| OpenAI o4-mini Deep Research | OpenAI | United States | closed | Tracked | mid | none on file |
| GPT-OSS 120B | OpenAI (served by Groq) | United States | open (Apache-2.0) | Standard work and long-form writing, May to September | low | independent |
| Voyage 3 | Voyage AI | United States | closed | Still called directly by the email sorter, outside the door (fix filed) | very low (input only) | none on file |
| Voyage 3 Large | Voyage AI | United States | closed | Tracked | very low (input only) | maker's own only |
| Voyage 3.5 | Voyage AI | United States | closed | Tracked | very low (input only) | maker's own only |
| Grok 4.20 | xAI | United States | closed | Tried in Cursor in March | mid | none on file |
| Grok 4.3 | xAI | United States | closed | On routes May to September; superseded by Grok 4.6 | mid | none on file |
| Grok 4.5 | xAI | United States | closed | Coding and research in Cursor, July to August; superseded by Grok 4.6 | mid | independent |
| MiMo V2.5 Pro | Xiaomi | China | open (factory-inferred-permissive) | Tracked only: models from Chinese labs are never routed | not captured | none on file |
| GLM 5.1 | Z.ai | China | open (MIT) | Tracked only: models from Chinese labs are never routed | not captured | none on file |
| Claude Opus 4.1 | Anthropic | United States | closed | Replaced by Claude Opus 4.6 | premium | none on file |
| Claude Opus 4 | Anthropic | United States | closed | Replaced by Claude Opus 4.6 | premium | none on file |
| Claude Opus 4.5 | Anthropic | United States | closed | Replaced by Claude Opus 4.6 | premium | none on file |
| Claude Opus 4.6 | Anthropic | United States | closed | Replaced by Claude Opus 4.7 | premium | maker's own only |
| Claude Sonnet 4 | Anthropic | United States | closed | Replaced by Claude Sonnet 4.6 | high | none on file |
| Claude Sonnet 4.5 | Anthropic | United States | closed | Replaced by Claude Sonnet 4.6 | high | none on file |
| Gemini Deep Research Pro Preview (December 2025) | United States | closed | Replaced by Gemini Deep Research Preview (April 2026) | mid | none on file |
Built from our model list each time this page is published. Price bands are relative, by blended price per million tokens. An independent score is one we read from a third-party scoreboard, dated.
Tomorrow: The steward that makes the no-brainer changes on its own, with the case laid out for the rest - and the search calls moved behind the door.
Models That Have Carried the Routes
Models come and go on the routes as scores and prices move. Here is every model that has carried real work through the door since the meter began in April 2026, with the job it did and when:
| Model | Maker | Job | When | What It Did |
|---|---|---|---|---|
| Claude Opus 4.7 | Anthropic | Standard work | April to August 2026 | 13,801 calls; 2,904.10 US dollars |
| Gemini 3.1 Pro Preview | Review | April to August 2026 | 3,159 calls; 207.35 US dollars | |
| GPT-5.4 | OpenAI | Deep reasoning | April to August 2026 | 816 calls; 65.94 US dollars |
| gpt-4o-mini-2024-07-18 | OpenAI | Called directly, before the door | April 2026 | 46 calls; 0.02 US dollars |
| GPT-5.4 | OpenAI | Standard work | May to August 2026 | 798 calls; 100.08 US dollars |
| GPT-5.5 | OpenAI | Deep reasoning | May to August 2026 | 697 calls; 104.43 US dollars |
| Gemini 2.5 Flash | Quick and bulk sorting | May 2026 | 12 calls; 0.08 US dollars | |
| Codestral 2508 | Mistral | Standard work | May to August 2026 | Core design calls and extraction; 193 calls; 35.33 US dollars. Off the routes since the September refresh, no independent score |
| Mistral Large 2512 | Mistral | Standard work | May to August 2026 | Core design calls and extraction; 131 calls; 26.45 US dollars. Off the routes since the September refresh, no independent score |
| GPT-5.4 mini | OpenAI | Quick and bulk sorting | Since June 2026 | 24,090 calls; 19.00 US dollars; still running in October 2026 |
| GPT-5.3 Codex | OpenAI | Standard work | June to July 2026 | 22 calls; 3.86 US dollars |
| GPT-5.4 mini | OpenAI | Quick and bulk sorting | July 2026 | 30 calls; 0.04 US dollars |
| Grok 4.3 | xAI | Standard work | July to August 2026 | 20 calls; 2.55 US dollars |
| Claude Opus 4.7 | Anthropic | Long-form writing | August 2026 | 66 calls; 2.98 US dollars |
| GPT-5.6 Terra | OpenAI | A trial, called directly | August to September 2026 | Direct trial, not a route; 370 calls; 7.41 US dollars |
The models on the routes today are listed above; their calls are metered under the route's name, so they join this table when they leave it.
The coding tools are a separate list: I pay for them by the seat, and which model each one runs is my call. Here is every model they have run since we started in February 2026:
| Tool | Model | Maker | When | What It Did |
|---|---|---|---|---|
| Claude Code | Claude Opus 4.5 | Anthropic | Until February 2026 | The Chief Architect |
| Claude Code | Claude Opus 4.6 | Anthropic | February to April 2026 | The Chief Architect |
| Claude Code | Claude Opus 4.7 | Anthropic | April to June 2026 | The Chief Architect |
| Claude Code | Claude Opus 4.8 | Anthropic | May to September 2026 | The Chief Architect |
| Claude Code | Claude Fable 5 | Anthropic | June to September 2026 | The Chief Architect |
| Claude Code | Claude Opus 5 | Anthropic | July to September 2026 | The Chief Architect and its helper sessions |
| Claude Code | Claude Fable 5.1 | Anthropic | September to October 2026 | The Chief Architect |
| Claude Code | Claude Opus 5.5 | Anthropic | Since late September 2026 | The Chief Architect, now |
| Claude Code | Claude Sonnet 4.6, Sonnet 5 and Haiku 4.5 | Anthropic | April to September 2026 | Research helpers |
| Codex | GPT-5.2-Codex | OpenAI | February 2026 | Coding |
| Codex | GPT-5.3-Codex | OpenAI | February to June 2026 | Coding |
| Codex | GPT-5.4 | OpenAI | March to June 2026 | Coding |
| Codex | GPT-5.5, at extra-high effort | OpenAI | April to July 2026 | Our main coding model: 373 sessions |
| Codex | GPT-5.6 Sol | OpenAI | July to September 2026 | Our main coding model: 313 sessions |
| Codex | GPT-5.6 Terra | OpenAI | July 2026 | A trial |
| Codex | GPT-6 Astra | OpenAI | Since September 2026 | Coding, and since September 13th the builds that run on their own: 225 sessions so far |
| Codex | GPT-6.1 Sol | OpenAI | Since October 1st, 2026 | A trial beside GPT-6 Astra |
| Cursor | GPT-5.2-Codex | OpenAI | Until February 2026 | Coding in the editor |
| Cursor | Grok Code Fast 1 | xAI | February to March 2026 | Coding in the editor |
| Cursor | GPT-5.5 | OpenAI | April to July 2026 | Coding in the editor |
| Cursor | Grok 4.5 | xAI | July to August 2026 | Coding and research |
| Cursor | Grok 4.6 | xAI | August to October 1st, 2026 | Coding in the editor, then research and reviews at the gate |
| Cursor | Grok 4.7 | xAI | Since October 1st, 2026 | Building and research, running on their own |
| Antigravity | Gemini 3 Pro | February 2026 | Quality reviews | |
| Antigravity | Gemini 3.1 Pro | March to September 2026 | Our quality architect: audits and acceptance | |
| Antigravity | Gemini 3.5, 3.6 and 3.7 Flash | May to August 2026 | Shorter stints | |
| Antigravity | Gemini 3.8 Flash | September 10th to October 1st, 2026 | The second reader at the gate |
A model that builds well isn't automatically a good reviewer, so when another lab's model is available, no file's review rests on one model alone.
Open Source, and When We Build Our Own
When Cleo and Dromeo's requirements point at a capability - reading a pose from a photo, drawing a chart, testing accessibility - the first question is whether someone has already built it well, in the open, under a license we can ship. Before anything gets built, a research pass fills in a short table: the candidates, each one's license, what we'd use as is, what we'd adapt, and one sentence for anything we'd build ourselves. It reads the sources it cites; nothing is decided from memory.
The license decides a lot. We take the permissive ones by default - MIT, Apache, BSD, ISC and MPL. GPL in anything that runs, AGPL anywhere and closed source are a no by default, and anything in between gets a written decision first. When we install something, we pin the exact version, keep its license and notice files beside it, and write down where it came from. Every outside skill our agents use is scanned when it's installed, and a skill is promoted only after it beats a baseline on at least ten test cases. We build our own when nothing open fits.
Take the fitness app. One requirement was to estimate a few body measurements from a single photo - on the phone, without the picture going anywhere. Any feature that uses the camera brings five privacy rules with it, and Cleo carries them as constraints: the photo stays on the phone, consent comes first, the feature is off by default, choosing the model gets its own review, and research comes before any vision work. (The app's requirements were written before it came into the factory, but the same rules applied.)
On September 16th a research pass compared the options, license first:
- Google's MediaPipe pose model (Apache 2.0) - chosen: one model on both phones, it runs on the device, and there's no per-use cost.
- MoveNet (Apache 2.0) - eligible, not chosen.
- Apple's vision framework on iPhone with MediaPipe on Android - turned down: two models means two sets of calibration.
- A popular YOLO pose model - ruled out: its AGPL license won't let a closed app ship it without buying a commercial license.
- Three ready-made React Native wrappers (MIT) - passed over: they lagged our versions of React Native and Expo, or only worked on live video.
We ship the model file exactly as published - pinned by its checksum, its license and notice beside it, nothing downloaded while it runs - inside our own small Swift and Kotlin module for still photos. Then our own accuracy test, run on synthetic mannequins rather than real people, said the estimate isn't good enough to stand on its own as a measurement. So it only fills in the boxes, you confirm with a tape measure, and it's switched on in preview builds only. The web version says plainly that the browser doesn't scan.
The rest of the app follows the same pattern: Expo's camera and photo picker with every permission it doesn't need removed; Apple Health through an MIT library, off until you turn it on; encryption on the phone with open libraries; and charts we drew ourselves on open SVG and animation libraries, after trying a charting library and dropping it the same day.
The Designosaurs work the same way. Their methods, and the themes on this page, are built on open work we can name and license:
| What | License | Who Uses It, for What |
|---|---|---|
| gstack, forked with its copyright kept | MIT | Cleo's founder-style review, Trully's QA and code review, Sun-sin's release checklist, Tycho's retrospectives |
| Superpowers | MIT | Ada's and Trully's test-first and debugging discipline |
| Ten engineering-process skills, pinned word for word | MIT | The agents that build the factory: requirements, triage, planning |
| drawio-skill | MIT | Tycho's editable diagrams |
| SkillSpector | Apache 2.0 | Scans every outside skill when it's installed |
| Anthropic's theme-factory | Apache 2.0 | Ten of our 36 themes, including this site's default |
| Open Design | Apache 2.0 | Two themes, including Brutalist Concrete on this page's switcher; with two other open collections, the reference library Dromeo and Trully design from |
| Floor-plan frames from MIT projects | MIT | The shells Ada and Dromeo fill instead of starting from a blank page |
| LiteLLM | MIT | The one door to the models |
| Playwright, browser-use, Crawl4AI | Apache 2.0, MIT, Apache 2.0 | Reading and measuring sites for Cleo and Dromeo |
| axe-core | MPL 2.0 | Trully's accessibility tests |
| Open typefaces | OFL and others | The faces our themes name, bundled as published |
| MAKER | A published method | Built in-house (next section) |
The other 13 themes we drew ourselves. And sometimes the answer is no: a self-hosted web crawler was turned down for its AGPL license (we use Crawl4AI instead); GNU FreeFont was refused for its GPL license; and when we looked at open-source customer-records tools on October 1st, the AGPL ones were out and the one clean option would have moved our records into a second database - so we built on our own records.
Why We Vote - and When We Don't
A model makes mistakes at random, and a long job made of many steps multiplies them. A November 2025 paper, "Solving a Million-Step LLM Task with Zero Errors" (arXiv 2511.09030), showed a way through, which its authors call MAKER: break the job into tiny steps, let several model calls answer the same step on their own, throw out any answer that comes back malformed, and take the first answer that gets K votes ahead of the runner-up. That way they finished a puzzle of more than a million dependent steps without a single error.
We took it up in April 2026, after our first end-to-end run, when five of our eight role agents crashed on malformed answers.
Then we measured. What made the builder reliable wasn't the voting - it was the compiler and the tests, with a repair loop when they fail. Voting on taste was holding up good work, and the paper itself only claims its result for steps with one right answer. So since June each kind of question has its own decider:
- When a machine test can settle it, whether it tests the code or the shape of the data, that result decides and nobody votes.
- When an answer has to come back in a fixed shape, the model is held to that shape as it writes.
- When there's one right answer and no test for it, the models vote: whether a security finding is real (Sun-sin), the ethics questions (Val), and whether a message holds a real event for my calendar.
- When it's a matter of taste, a real, live human being decides what looks and feels right. The model's score is advice, and each of those calls is saved as an example the system can learn from.
How the count works: with three voters and K of two, the leader has to be two votes ahead. Three to nothing wins; two to one doesn't. A malformed answer is thrown out before counting, so two to nothing with one thrown out also wins - in practice, every answer that counts has to agree. When a vote can't settle it, the question is held for a person; nothing goes through on a split.
We also stopped voting where it wasn't paying. When every piece of generated code was voted on three times, the votes caught nothing the tests hadn't. Now one model writes each piece, and a failed test sends just that piece to a three-way vote.
Today the calendar reader votes every minute, asking models from different makers, and an event still waits for my OK before it lands on my calendar. The other votes run when an app is being built. We haven't measured our own error rate with and without voting, so we don't quote one.
How the Work Gets Done
Several AI coding agents work on the software in parallel, each on its own copy of the code, so a day's work is done in a day. Nothing they produce goes into the product until I have seen it work on real data in a real browser. Every release goes through three stages and leaves a record of what was tested and who approved it. When something is wrong it gets fixed the same day.
The Designosaurs™
Nine behind-the-scenes agents split the work the way a software company splits it: strategy, design, code, review, records, release, health, and the conductor who keeps time.
Meet each of them on the Designosaurs page.
Numbers We Can Show
Real counts from our own systems, each dated. Nothing is rounded up.
| Measure | Value | As of |
|---|---|---|
| Changes shipped in one week | 128 | |
| Releases to production in one week, each with a record | 7 | |
| Defects found in production and fixed the same day | 9 of 9 | |
| Emails read and sorted by the system | 103,928 | |
| Text messages read alongside them | 33,545 | |
| Events spotted in my email and texts that I might otherwise miss | 240 spotted · 7 added to my calendar · 25 dismissed | |
| Visual themes ready for any app (each app ships with three, switchable while it runs) | 25 |
Learning the Math
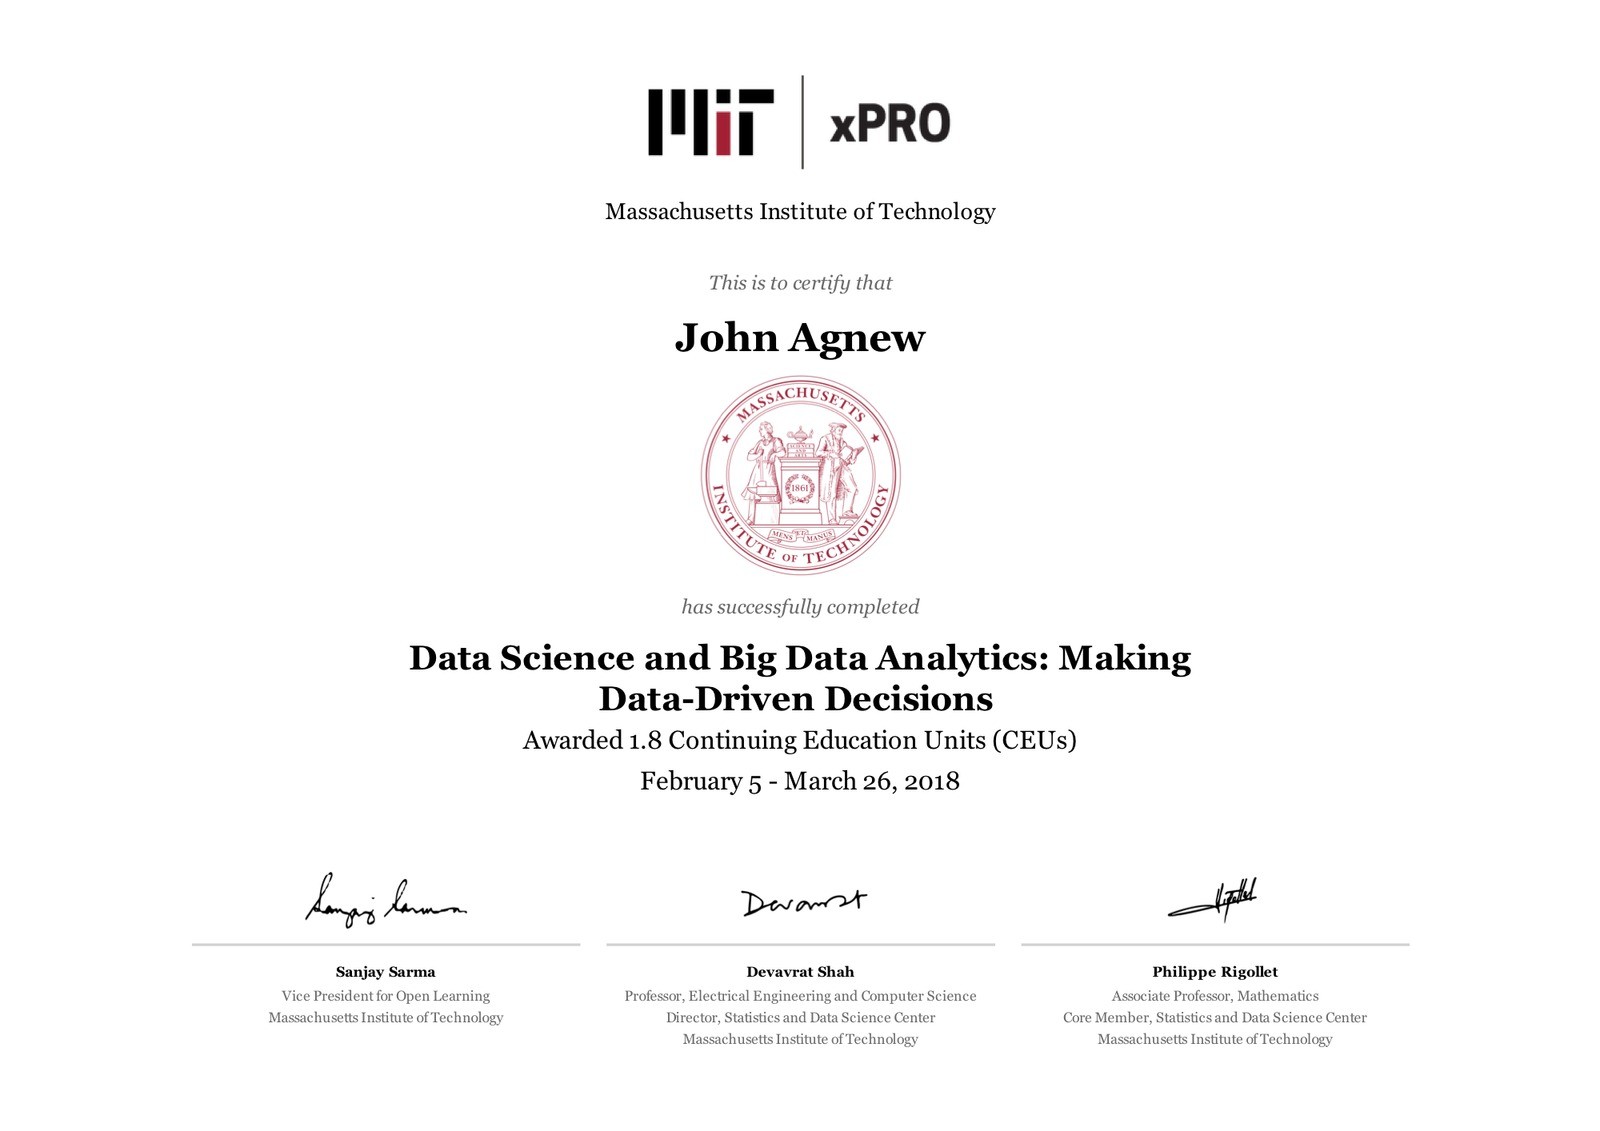
MIT xPRO, Data Science and Big Data Analytics: Making Data-Driven Decisions, certificate, February 5th through March 26th, 2018, through a joint Landmark and MIT program for which I was selected.
I didn't know the math that turned out to be a prerequisite for the course. I learned linear algebra and Python on my own time so I could finish the course.
At Landmark I learned Python and machine-learning techniques, built a forty-three-account field-development sales plan with a customer and sold the project to several companies, and a second plan for a production project.
Talend Data Fabric Explorer foundations learning plan, September 20th, 2021 (Qlik / Talend via Credly).
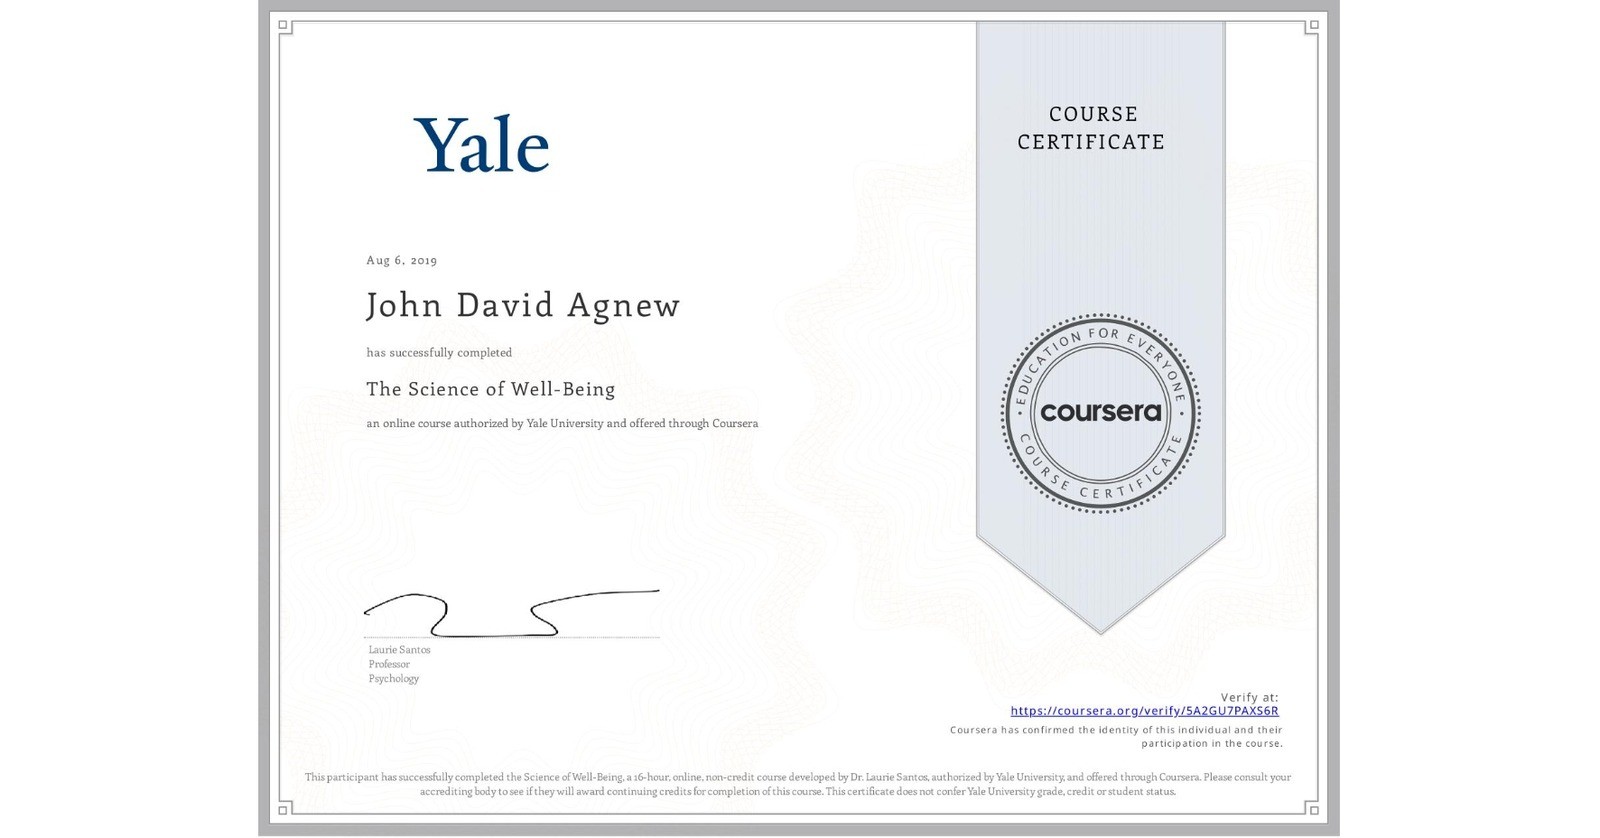
The Science of Well-Being, Yale University, twelve hours on Coursera, completed August 6th, 2019.
Method and Reading
Methodologies I use: BANT; MEDDIC; SPIN Selling; The Challenger Sale; consultative and solution selling.
Books on my shelf: The Challenger Sale; SPIN Selling; Fanatical Prospecting; a title on buyer enablement I keep coming back to.
Articulus Corporate Storytelling workshop, July 2018, sponsored by Halliburton.
More
What we build · Trio Themes · Positioning · Differentiators · The Designosaurs · How it works